On Speech Recognition Model Adaptation and Accuracy Calibration for Oral History Archives
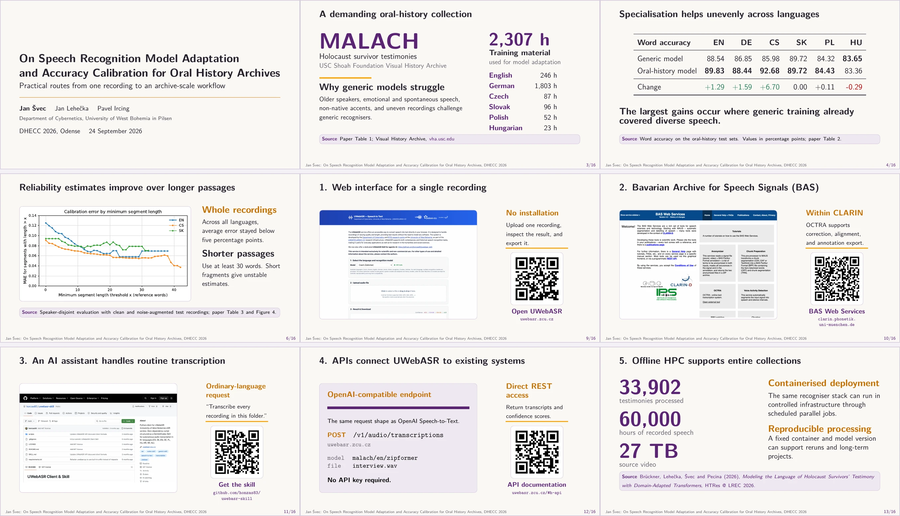
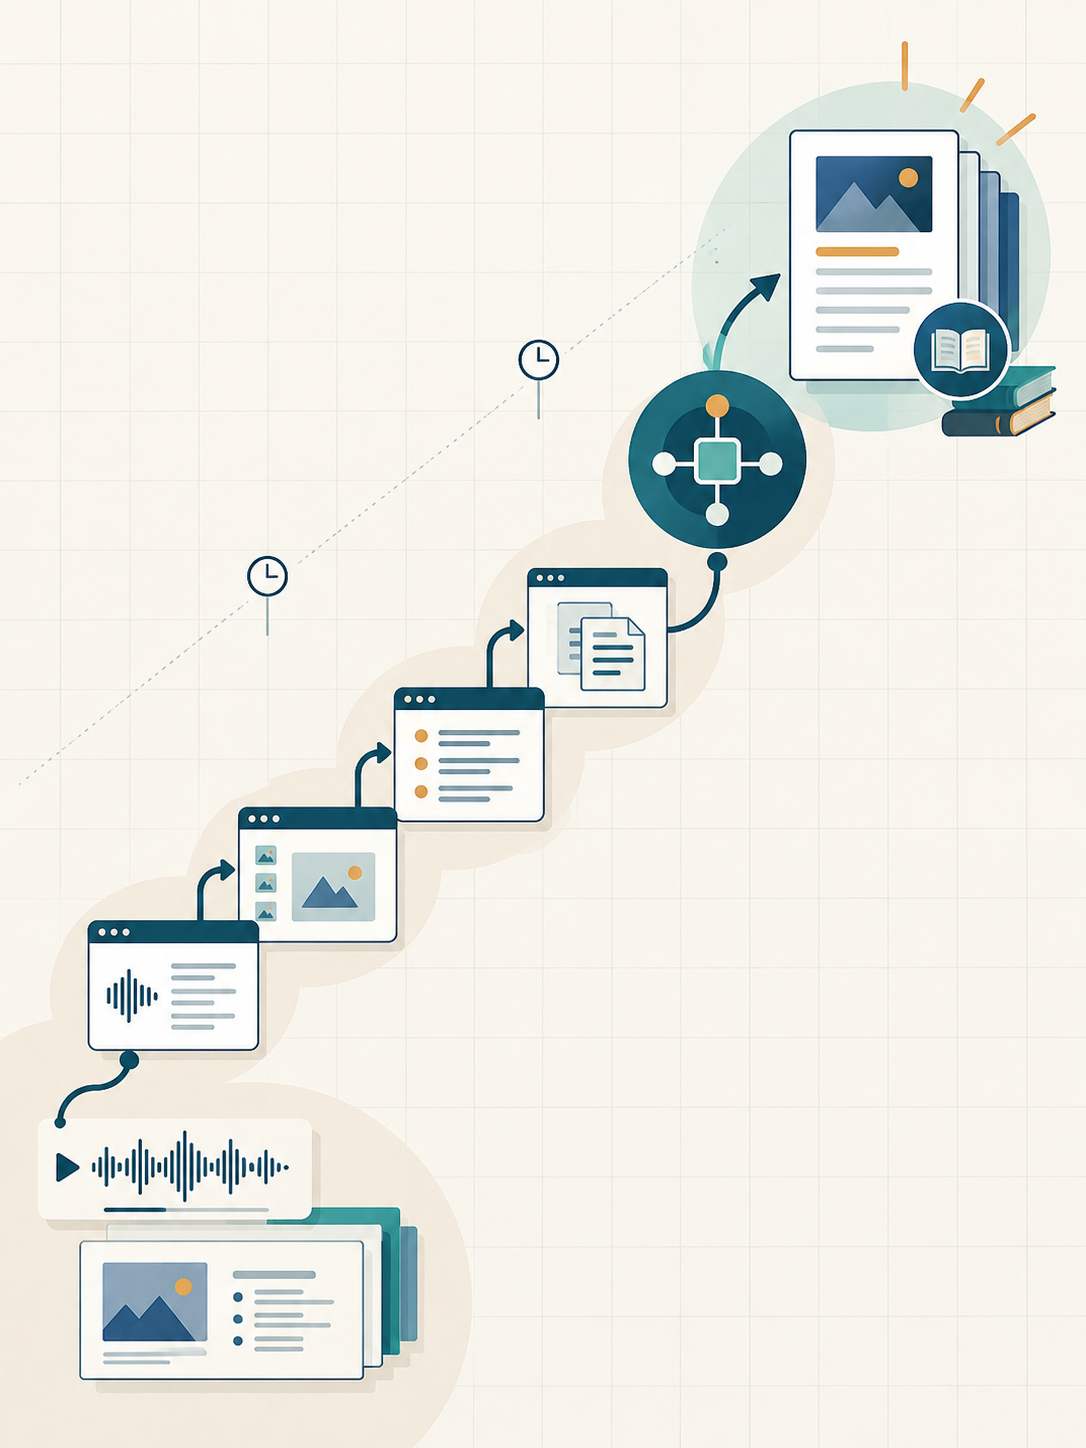
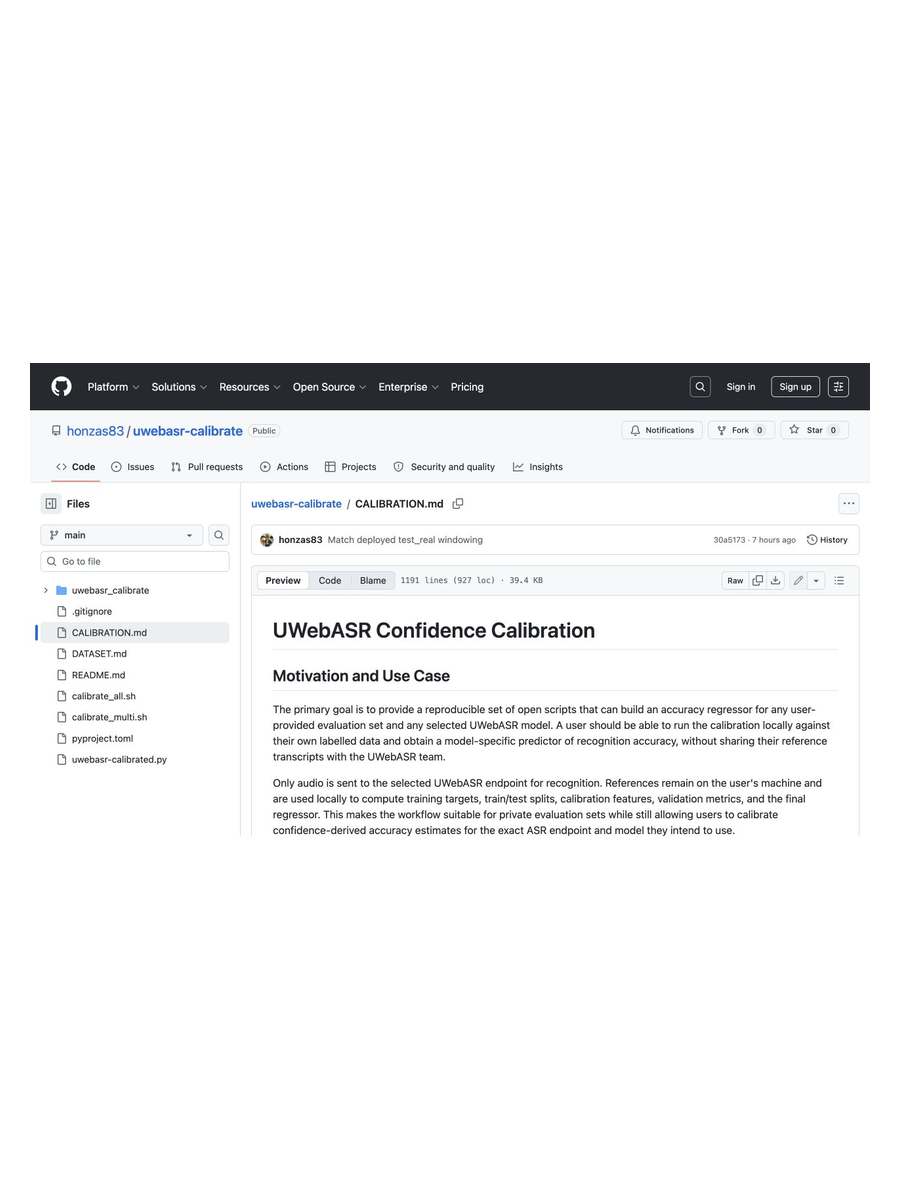
Large oral-history collections become searchable once speech is converted into time-aligned text, yet researchers still need a practical way to judge transcript reliability. At DHECC 2026 in Odense on 24 September, I presented our paper on adapted speech-recognition models and calibrated accuracy estimates for six languages, co-authored with Jan Lehečka and Pavel Ircing. Conference attendees can find the presentation here together with direct links for using UWebASR in a browser, through BAS, with an AI assistant, via APIs or on offline HPC infrastructure.