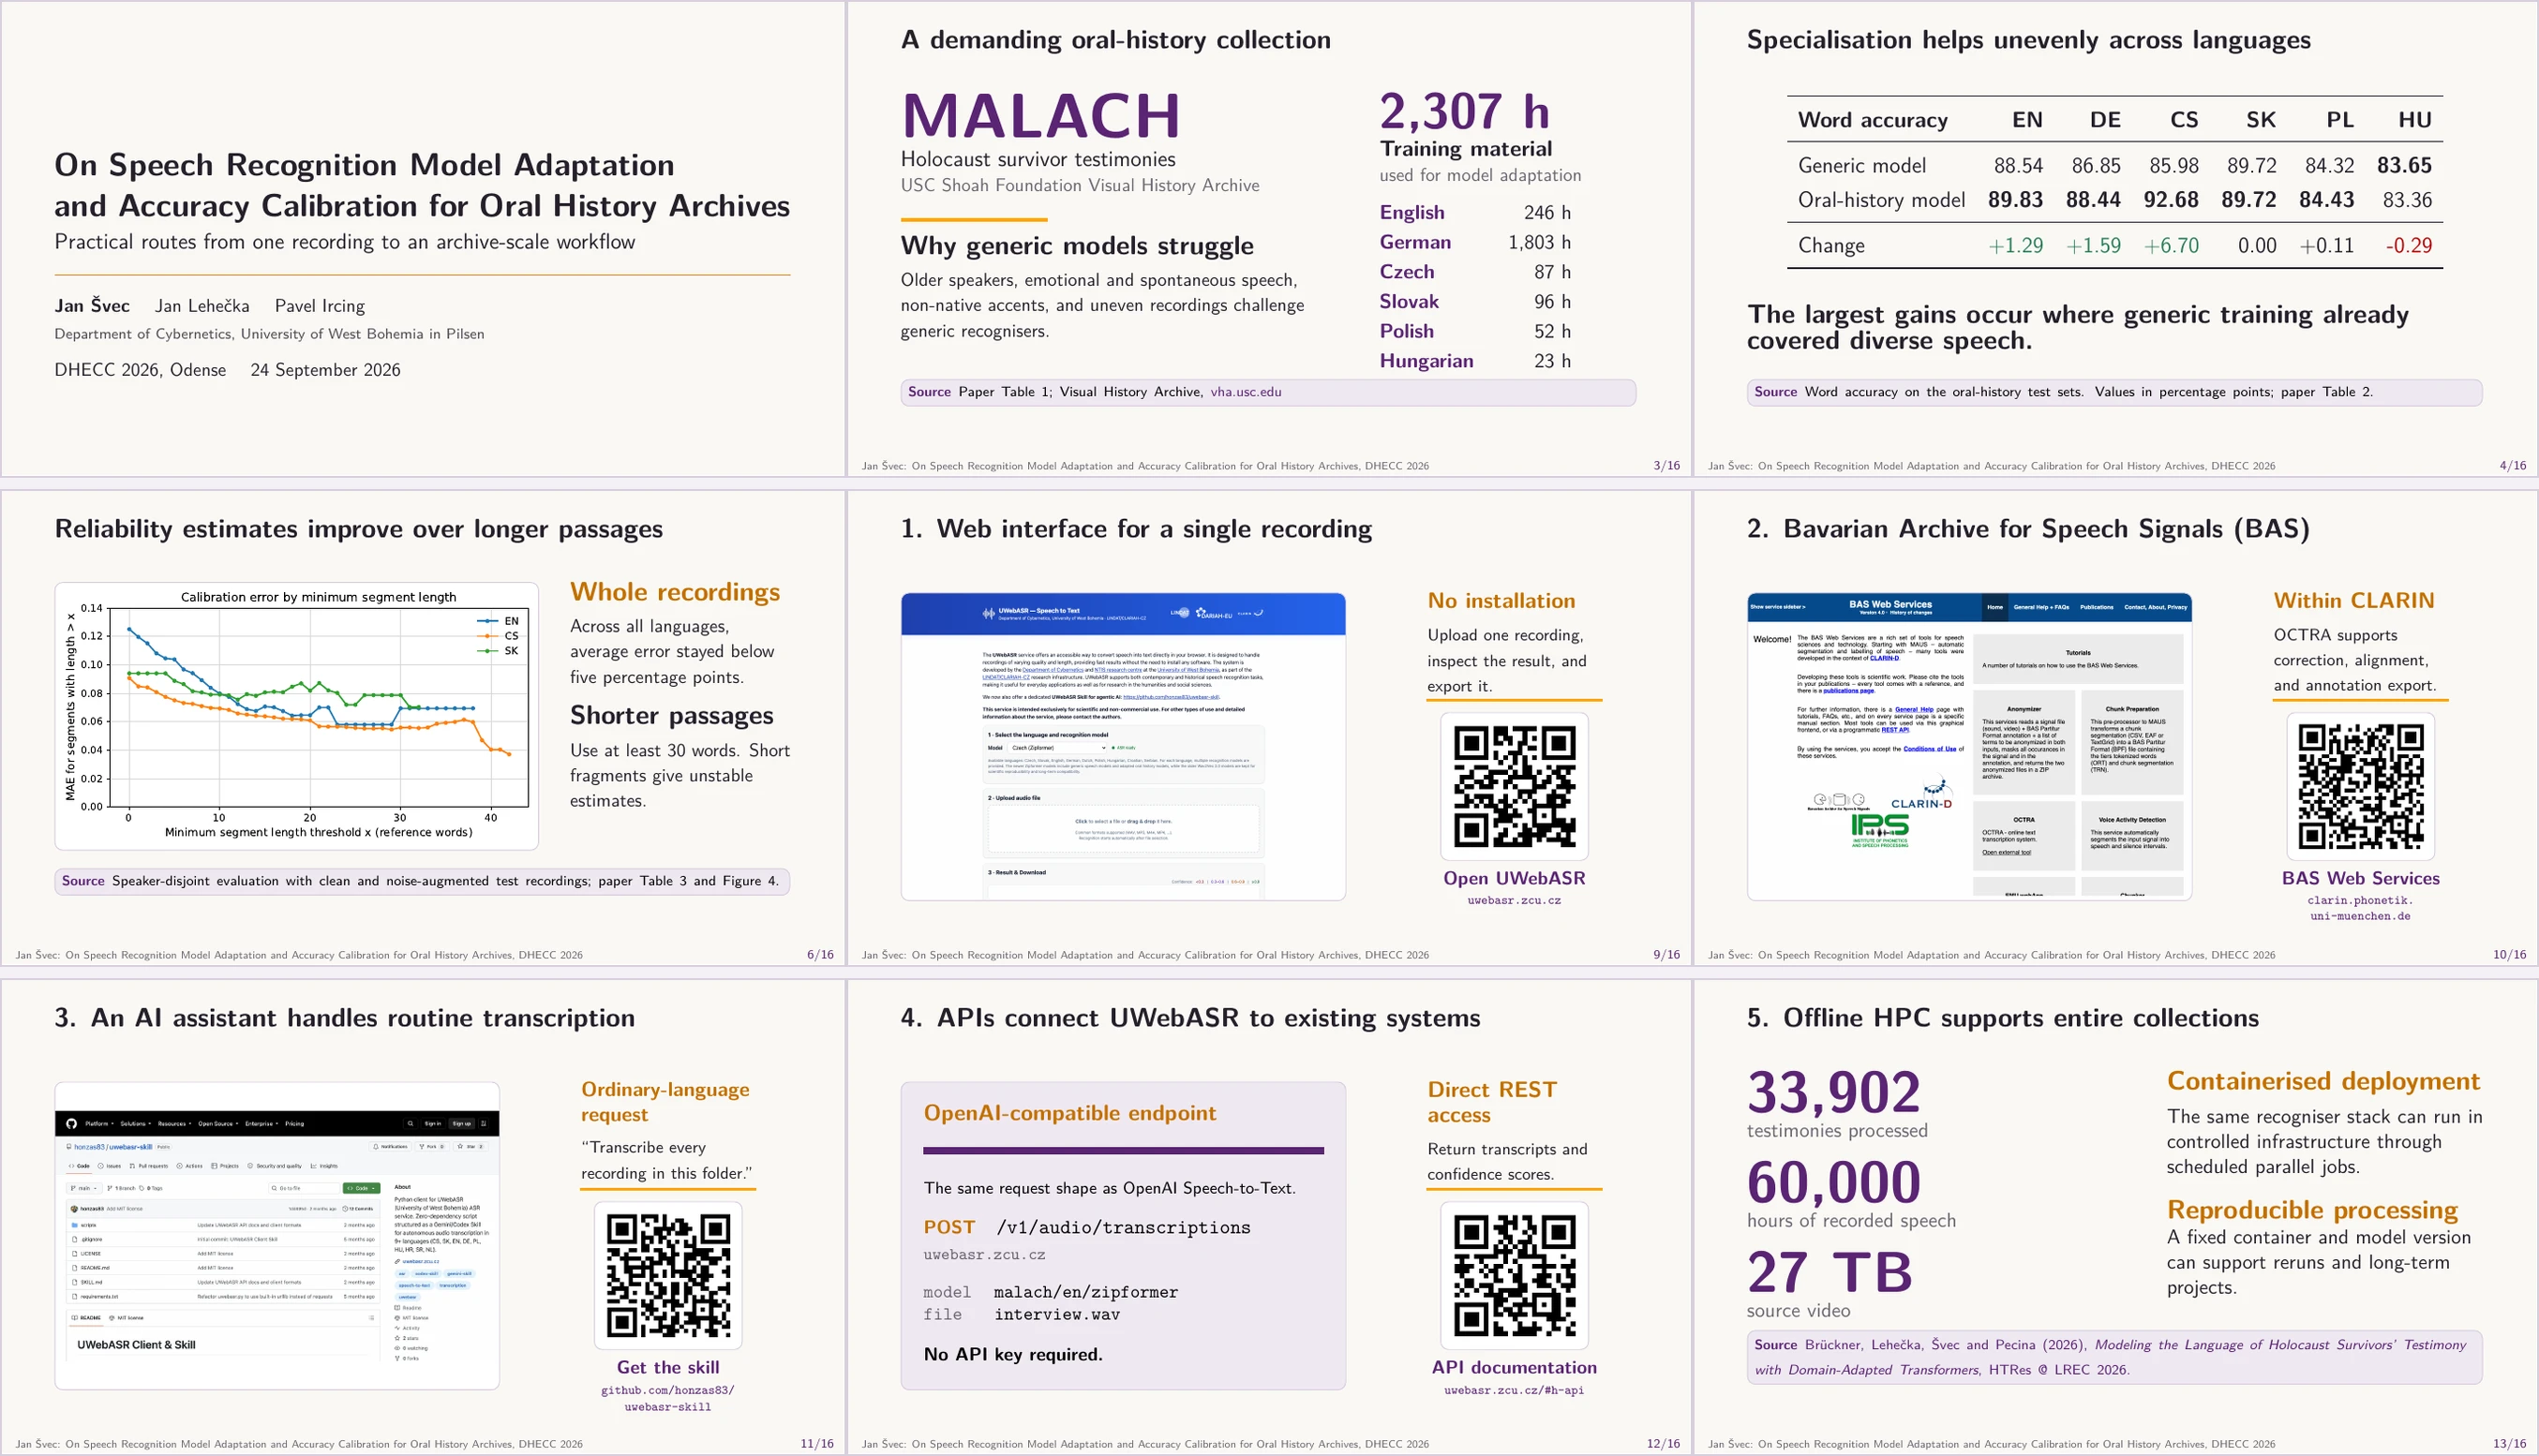
Large oral-history collections become searchable once speech is converted into time-aligned text, yet researchers still need a practical way to judge transcript reliability. At DHECC 2026 in Odense on 24 September, I presented our paper on adapted speech-recognition models and calibrated accuracy estimates for six languages, co-authored with Jan Lehečka and Pavel Ircing. Conference attendees can find the presentation here together with direct links for using UWebASR in a browser, through BAS, with an AI assistant, via APIs or on offline HPC infrastructure.
The first paper session of the Digital Heritage of European Conflicts Conference 2026 brought together four approaches to computational analysis of conflict heritage. In the DIAS Auditorium at the University of Southern Denmark, I presented our work on speech recognition for oral-history archives; Jan Lehečka and Pavel Ircing are co-authors of the paper.
The presentation followed our recently published International Journal of Digital Humanities paper. It moved quickly from the research results to a practical question: how can a researcher, developer or archive actually use the recogniser?
From a transcript to a reliability estimate
The models were adapted to Holocaust survivor testimonies in English, German, Czech, Slovak, Polish and Hungarian. Adaptation improved the results unevenly across languages, with the largest gain in Czech. That unevenness is useful information in itself, because the quality and diversity of the generic training base matter as much as the existence of domain-specific data.
UWebASR can also add a model-specific estimate of expected word accuracy. At the level of whole recordings, the average calibration error stayed below five percentage points across all six languages in our evaluation. Short fragments remain unstable, so important names, places and quotations still need to be checked against the recording.
Five ways to use UWebASR
The second half of the talk showed five ways to use UWebASR for transcribing recordings. The suitable option depends on collection size, the surrounding workflow and the data-governance requirements set by the collection owner.
- Web interface - upload one recording in a browser, inspect the confidence information and accuracy estimate, then export the transcript in several formats.
- BAS Web Services - use UWebASR inside an established CLARIN environment with tools for alignment, correction and annotation export.
- AI assistant - give an ordinary-language instruction such as “transcribe every recording in this folder” and let the public UWebASR skill handle the routine steps.
- HTTP and OpenAI-compatible APIs - connect the recogniser to an existing application and receive transcripts together with confidence information. The OpenAI-compatible endpoint uses the familiar
/v1/audio/transcriptionsrequest shape and requires no API key. - Offline HPC processing - run the same recogniser stack in infrastructure controlled by the collection owner. We provide a Singularity/Docker image for reproducible parallel processing on HPC systems, including large or restricted collections.
The public UWebASR service handles audio and recognition results on University of West Bohemia infrastructure for the duration of the recognition session. Uploaded recordings and generated transcripts are not retained after the session ends. Restricted collections may require offline processing under the collection owner’s control; the collection policy remains the deciding authority.
Presentation and paper
The complete presentation includes the results, QR codes and direct links used during the talk. The paper is available through its DOI record and as full text on SharedIt. The earlier calibration article describes how the method moved from a proof of concept into production.
Links
- Presentation: The complete presentation PDF used at DHECC 2026 on 24 September 2026.
- Published paper: The peer-reviewed International Journal of Digital Humanities article behind the presentation.
- Full text on SharedIt: Publisher-provided SharedIt access to the full paper.
- DHECC 2026 programme: The two-day conference programme, including the Computational Analysis of Conflict Heritage session.
- UWebASR web interface: Browser access for uploading one recording, inspecting the transcript and exporting the result.
- BAS Web Services: CLARIN-connected tools for alignment, correction and annotation workflows.
- UWebASR Client & Skill: A public agent skill and Python client for transcribing files and folders through UWebASR.
- UWebASR API documentation: HTTP and OpenAI-compatible API access for integrating transcription into existing systems.
- Offline HPC deployment: The HTRes 2026 paper describing archive-scale processing of 33,902 testimonies in controlled infrastructure.
- From UWebASR to calibrated accuracy estimates: A practical account of the calibration workflow and its deployment in UWebASR.